For files with multiple pages. Split and categorize docs on a per-page basis.
Enhance processing speed through multi-page context that isolates documents inside multi-page files.
14-day free trial


4.8/5 (30+ reviews)
Trusted by top-tier teams worldwide

Without

Splitter
Generalist LLMs struggle with structural speed, requiring heavy resource overhead to deliver accurate splitting results

Prone to missing boundaries in long files
You pay for thousands of tokens just to find a "page break"
Difficult to admit when it's "unsure" of a type

With

Splitter
+95%
Document-level split accuracy
Handles 1-page receipts and 50-page contracts.
Scans and slices a 100-page batch in milliseconds
Built-in metrics to trigger human review only when needed
Trained on millions of real-world business documents
Implement “Splitter” into your document workflow, in seconds

Available for every plan
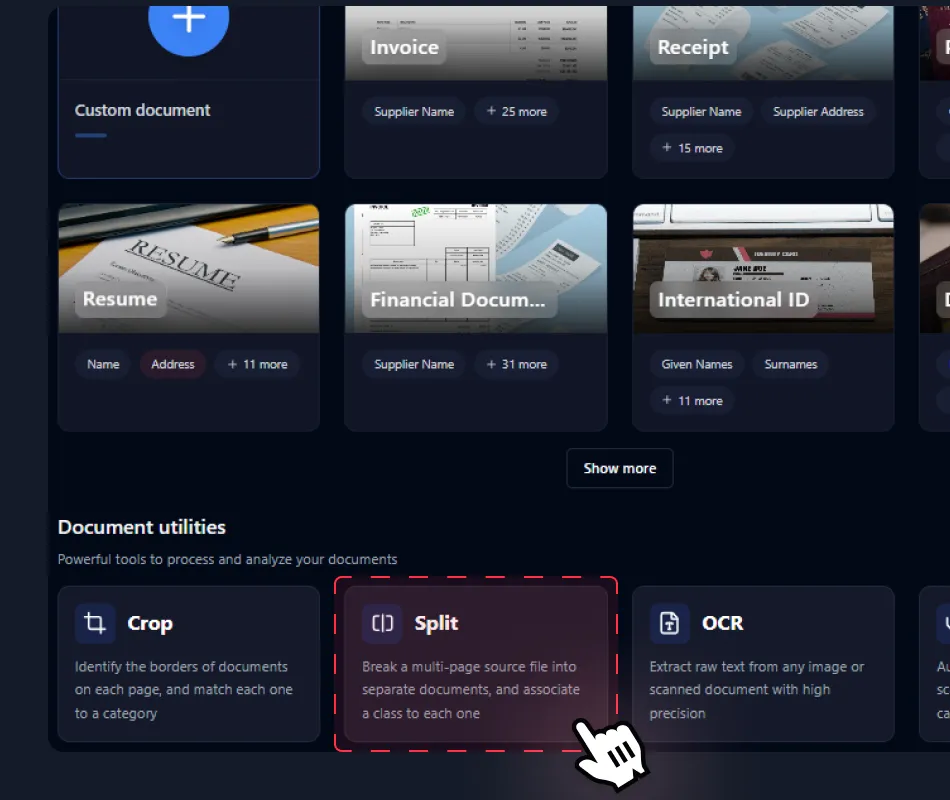
From Mindee’s platform, create a new pre‑processing model by clicking on “Splitter” utility
You will find it at the bottom of the user interface. If you are more familiar with this type of pre-processing model, you can directly use it by checking the Documentation for more details.
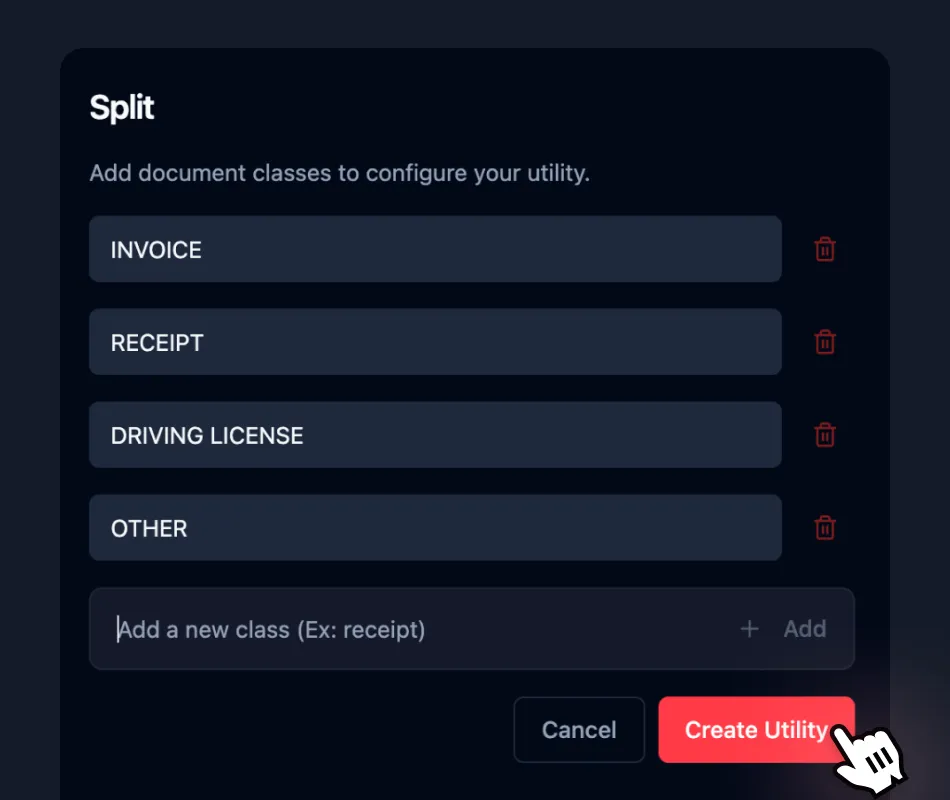
Custom to your needs
Enter the document categories that correspond to your needs
Before final pre-processing, you need to define appropriate categories. Be sure to manually add an “Undefined” category. If a file doesn’t match to your document main categories, it will be available in the “Undefined” one.
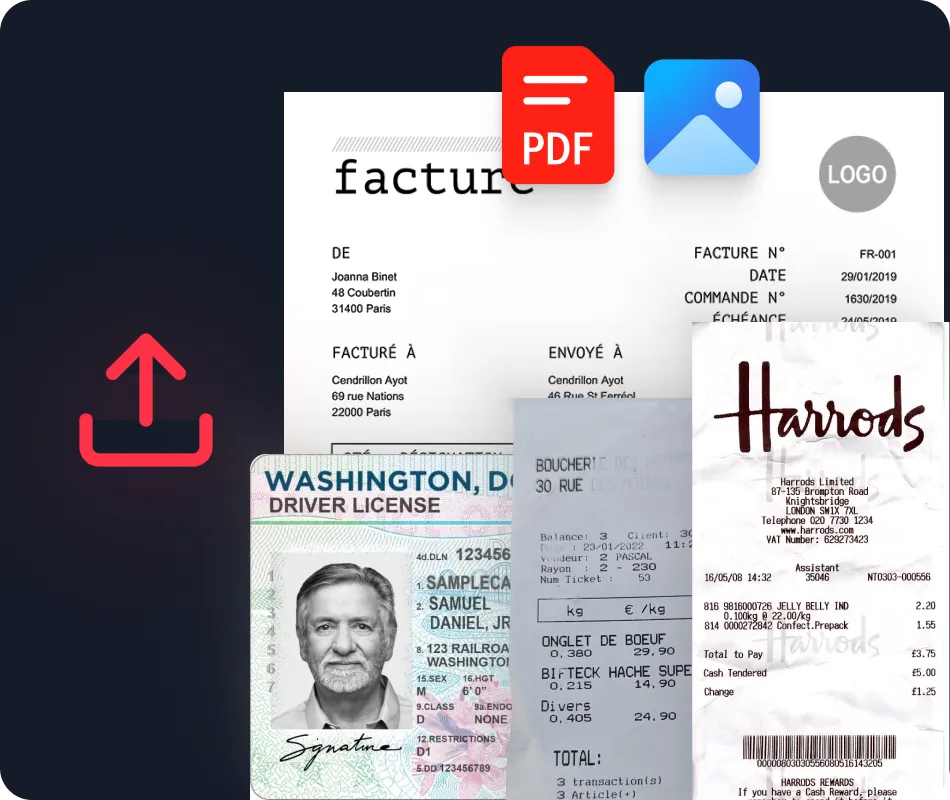
PDF, HEIC, PNG, JPEG... MUltiple formats
Upload your documents without friction: universal PDF and image support
Accelerate ingestion with native support for PDFs and all image formats. From high-res scans to mobile captures, Mindee API handles any input, ensuring your data is always ready for extraction.
full document processing stack
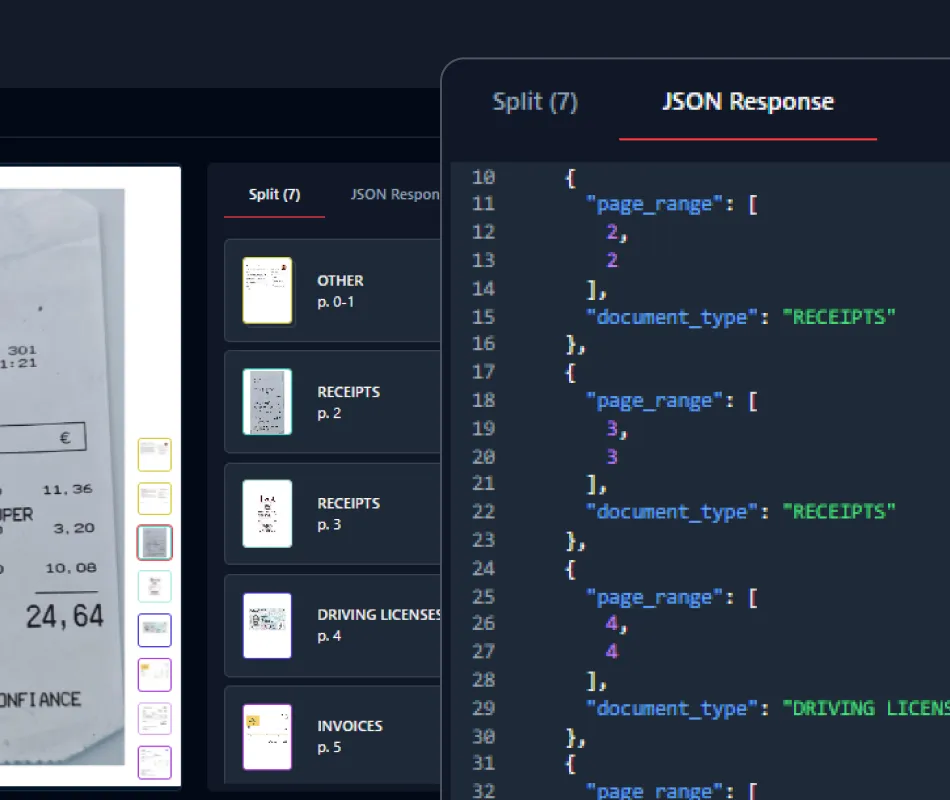
Find all your files categorized in standard JSON format, ready for extraction based on categories
Pre-processing via auto-split can then be combined with other Mindee’s API features to further improve the granularity or directly extract data based on each category classification.
How automated document data extraction APIs work
Five steps run behind Mindee's API, from a blurry phone photo to validated JSON your systems can trust. Pick a step to see what happens.
Smart capture, from poor phone pictures to native PDFs
Bridge the gap between noisy inputs and structured data. Mindee reads low-quality phone captures, handwritten notes and native PDFs alike, and isolates several documents shot on a single picture.
- Phone photos, scans and multi-page PDFs
- Document borders detected automatically
Split and classify before a single field is read
A 40-page scan from the office printer, three receipts on one photo, invoices mixed with credit notes: Mindee finds where each document starts, labels its type and sends it to the right model.
- Page ranges for every detected document
- Your own document classes for routing
Layout-aware extraction, down to every table row
Mindee reads the page the way a person does: it understands headers, columns and line items, then returns each value as structured JSON with its coordinates on the document.
- Key-value pairs, tables and line items
- Bounding box for every extracted value
Typed, normalised values your systems accept as is
Dates, amounts and codes come back in consistent formats whatever the document's language. Classification fields defined in your data schema add context the page never states, like an expense category.
- Date, number, boolean and string types
- Classification fields you define
A confidence score on every field, and your threshold
Trusted values flow straight to your ERP or database. Anything below your threshold goes to a person, with its exact spot on the page highlighted. Drag the slider to try it.
- Auto-approve what you can trust
- Results pushed by webhook when ready
Integrate Mindee into your workflow in minutes with SDKs & no-code tools
Go live in minutes using our verified Zapier & Make.com app with zero coding, or integrate seamlessly via our well-documented REST API built for developers. SDKs available for Python, .NET, Node.JS, Java, Ruby, PHP.
Integrations

Enterprise-grade security
Our API has a SOC 2 Type II certified infrastructure and is GDPR Compliant to ensure your file information remains protected at all times.

EU or US hosting available

GDPR, CCPA Compliant
Learn more
Developers and technical profiles already used it !
Add modern AI-based Mindee OCR API to your product, in minutes.

Mindee is an integrated document processing platform backed by reliable AI technology. The service has an intuitive and user-friendly interface and provides highly accurate results extracting data from various document types, especially financial receipts and invoices, which are relatively complex for efficient data extraction and automation.

Amar A.

Mindee is a software that helps us to convert all of our physical business data like bills, invoices, warranty cards, calendar, recipts received to us into a digital documents that can be stored in our drive and can be uploaded in different type of Excel sheets so that all the updates can be maintained and a proper analytics of transactions can be kept by the financial team
Shiv K.
Mindee is a web based tool that help us in scanning and reading different type of documents like identity cards, invoices, proposal plans etc and extract all the information with its AI and then it provides all the information and data associated with these documents a structured way.
Gaurav K.
Excellent. In addition to their great product, the sales team has always been proactive on how they could help us leverage the maximum results from their product. It was like having an additional product manager on our side

Jeff B.
Mindee works reliably and delivers good performance. The OCR data is accurate, and the API is stable. It works like a charm.
Manuel B.

I like the easiness and how to use it. Also the price model is very fair. Good with space for improvement
Simon
+15M documents processed monthly
Start to use Splitter now.
+500 active users
SOC 2 Type II & GDPR
No credit card required
FAQ about Mindee's OCR API
What is automated document splitting?

Automated document splitting is a pre-processing technology that analyzes multi-page file uploads (like a 50‑page PDF) and automatically breaks them down into separate, logical documents. Instead of a human manually reviewing a file to see where one invoice ends and another begins, the AI detects document boundaries—based on layout changes, page numbering, or content shifts—to split the batch into distinct, standalone records ready for data extraction.
What are examples of automated document splitting?
Automated splitting finds where each document starts and ends inside a single file, so every one can be processed as its own record. Common examples:
Accounts payable: A vendor sends one PDF with dozens of invoices and credit notes. Each one is split out and processed individually.
Two-way matching and reconciliation: A single scan contains a purchase order and its delivery note. Splitting them lets the two be cross-referenced automatically for audits.
Customer onboarding: A new client uploads one file with their ID, a utility bill, and a signed contract. Each document is split out and sent to the right extraction model for verification.
Vehicle fleet management: Maintenance folders often mix insurance certificates, logbooks, and repair invoices. Each document is identified and filed under the right vehicle with no manual sorting.
See more examples in our customer stories.
How does automated document splitting work?
Mindee’s splitting solution uses a multi-layered approach to ensure perfect "document boundaries."
- Visual continuity analysis: The AI looks for visual cues, such as consistent headers, logos, or page footers (e.g., "Page 1 of 3").
- Logical boundary detection: It identifies "breaking points," such as a new invoice number, a different date, or a sudden change in document layout (e.g., shifting from a legal contract to a utility bill).
- Batch decomposition: Once the boundaries are confirmed, the system "cuts" the multi-page file into separate digital records.
How to auto-split a multi-page source file into separate documents?
Manually splitting PDFs is a massive productivity killer. To automate this, you should implement an API with native splitting capabilities rather than trying to build custom logic in Python.
Mindee’s splitter feature handles this within the API call itself.
When you upload a batch file, the solution detects the record boundaries and provides a structured output of separated documents. This allows developers to build "one-click" upload features where users can drop an entire day's worth of paperwork into a single box, and the system handles the sorting, splitting, and extraction in the background.
