Tabla de Contenidos

La instantánea
If you clicked through from our recent announcement, you already know that custom model creation just got a massive upgrade. But let’s look at the mechanics behind this update and how it solves one of the most common friction points in AI data extraction: the gap between a single sample document and your actual business logic.
The "too specific" trap
Our platform data revealed a clear trend: over 80% of our users prefer bootstrapping a model by uploading a sample file rather than starting from scratch with a conversational prompt. However, the legacy system had a blind spot. It was often too literal.
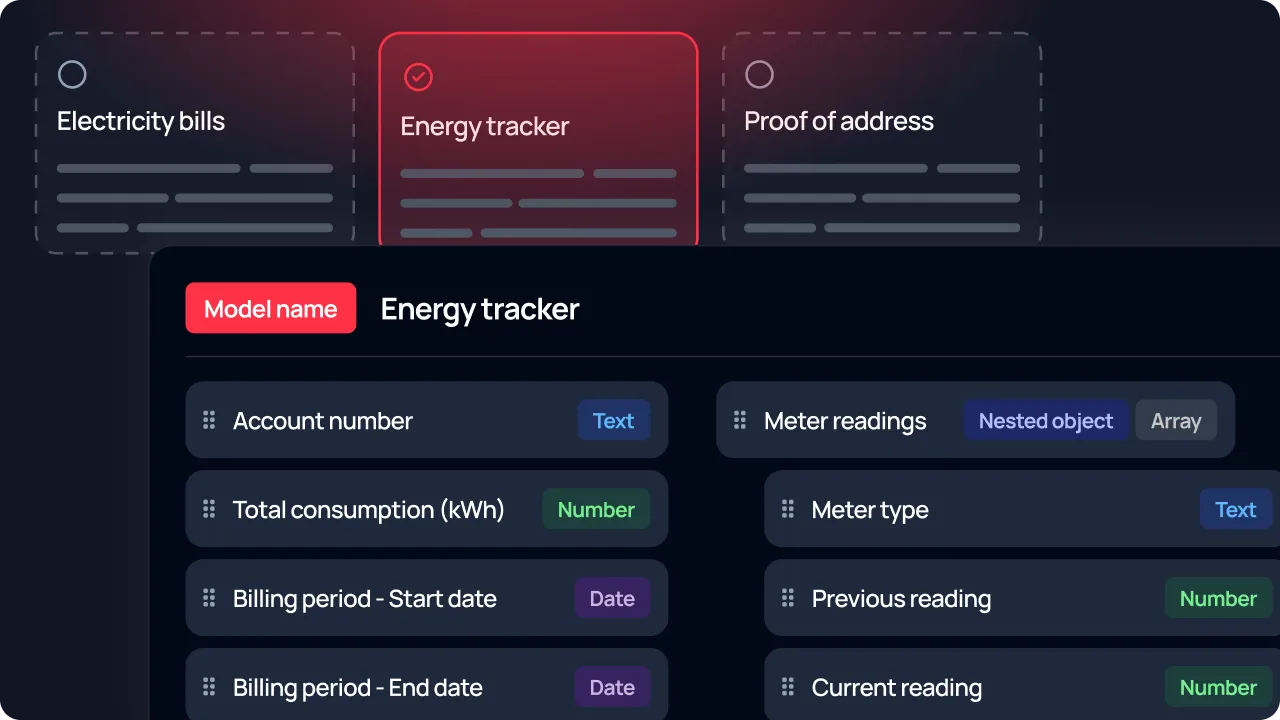
If you uploaded an electricity bill, the AI historically built a rigid data schema strictly optimized for energy bills. But in reality, your software likely needed a broader model capable of validating any proof of address, whether it’s a electricity bill, a phone invoice, or a tax document.
This mismatch meant users had to spend valuable development time manually deleting specific fields and refining the schema to broaden its scope. We knew there had to be a more intuitive way.
How intent prediction changes the game
We completely re-engineered the onboarding flow to anticipate your true objective before finalizing the schema. Here is how the new engine works behind the scenes to eliminate configuration frustration:
- Multi-document pattern recognition: You can now upload up to 10 diverse sample documents upfront. The AI cross-references these files to identify structural variations and common underlying data points.
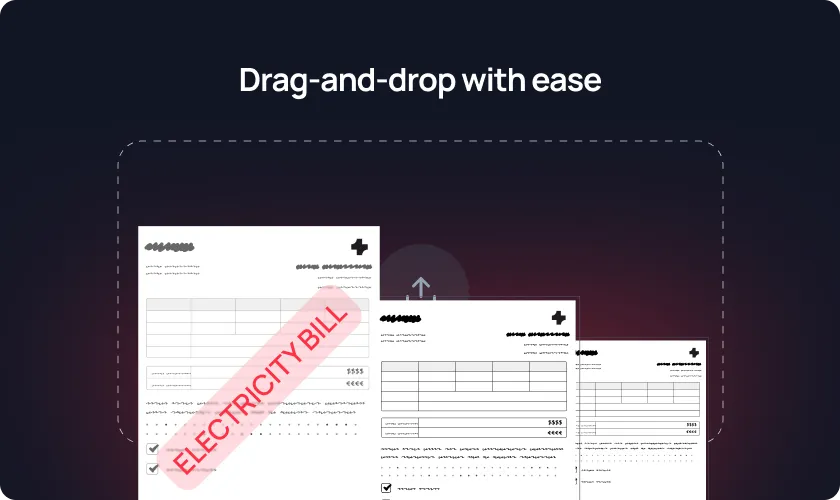
- Contextual triangulation: Instead of forcing one rigid assumption, the engine maps your documents against our vast catalog of extraction scenarios and suggests 3 distinct, highly relevant use cases.
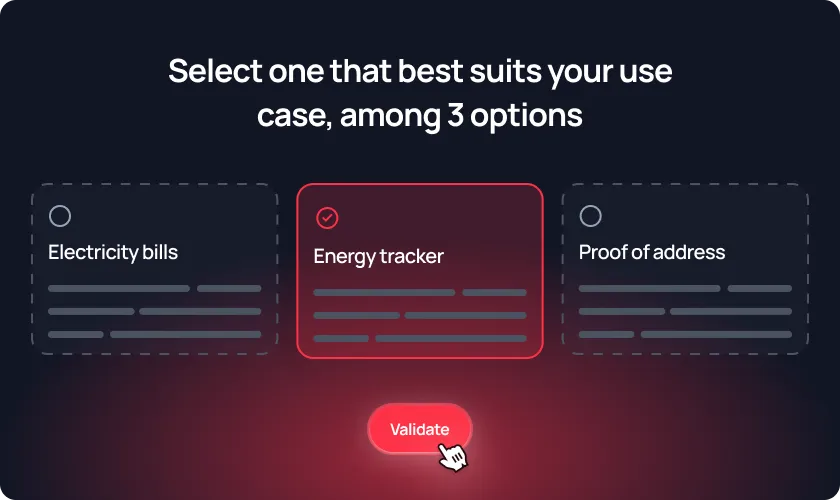
- Dynamic schema generation: Once you select the path that aligns with your exact business logic (e.g., choosing "Energy tracker" instead of "Proof of Address"), the AI re-analyzes the files to generate a perfectly tailored, comprehensive schema.
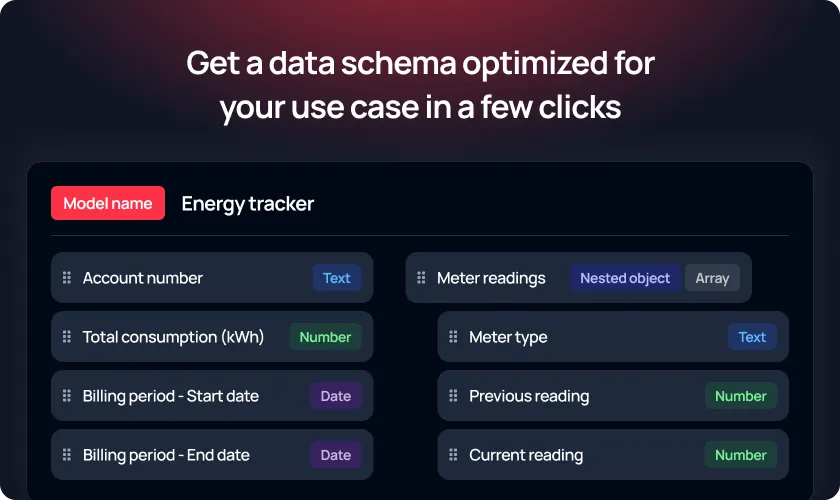
This update dramatically reduces the time it takes to go from raw files to a production-ready model. By bridging the gap between a visual file type and your underlying business intent, your models become highly reliable from day one, requiring near-zero manual configuration.
Head over to your Mindee workspace and give the new workflow a spin!
Remind what specific document type has historically caused the most schema configuration headaches for your team?
Acerca de